
Heabsy AI Inference
What is Heabsy AI Inference?
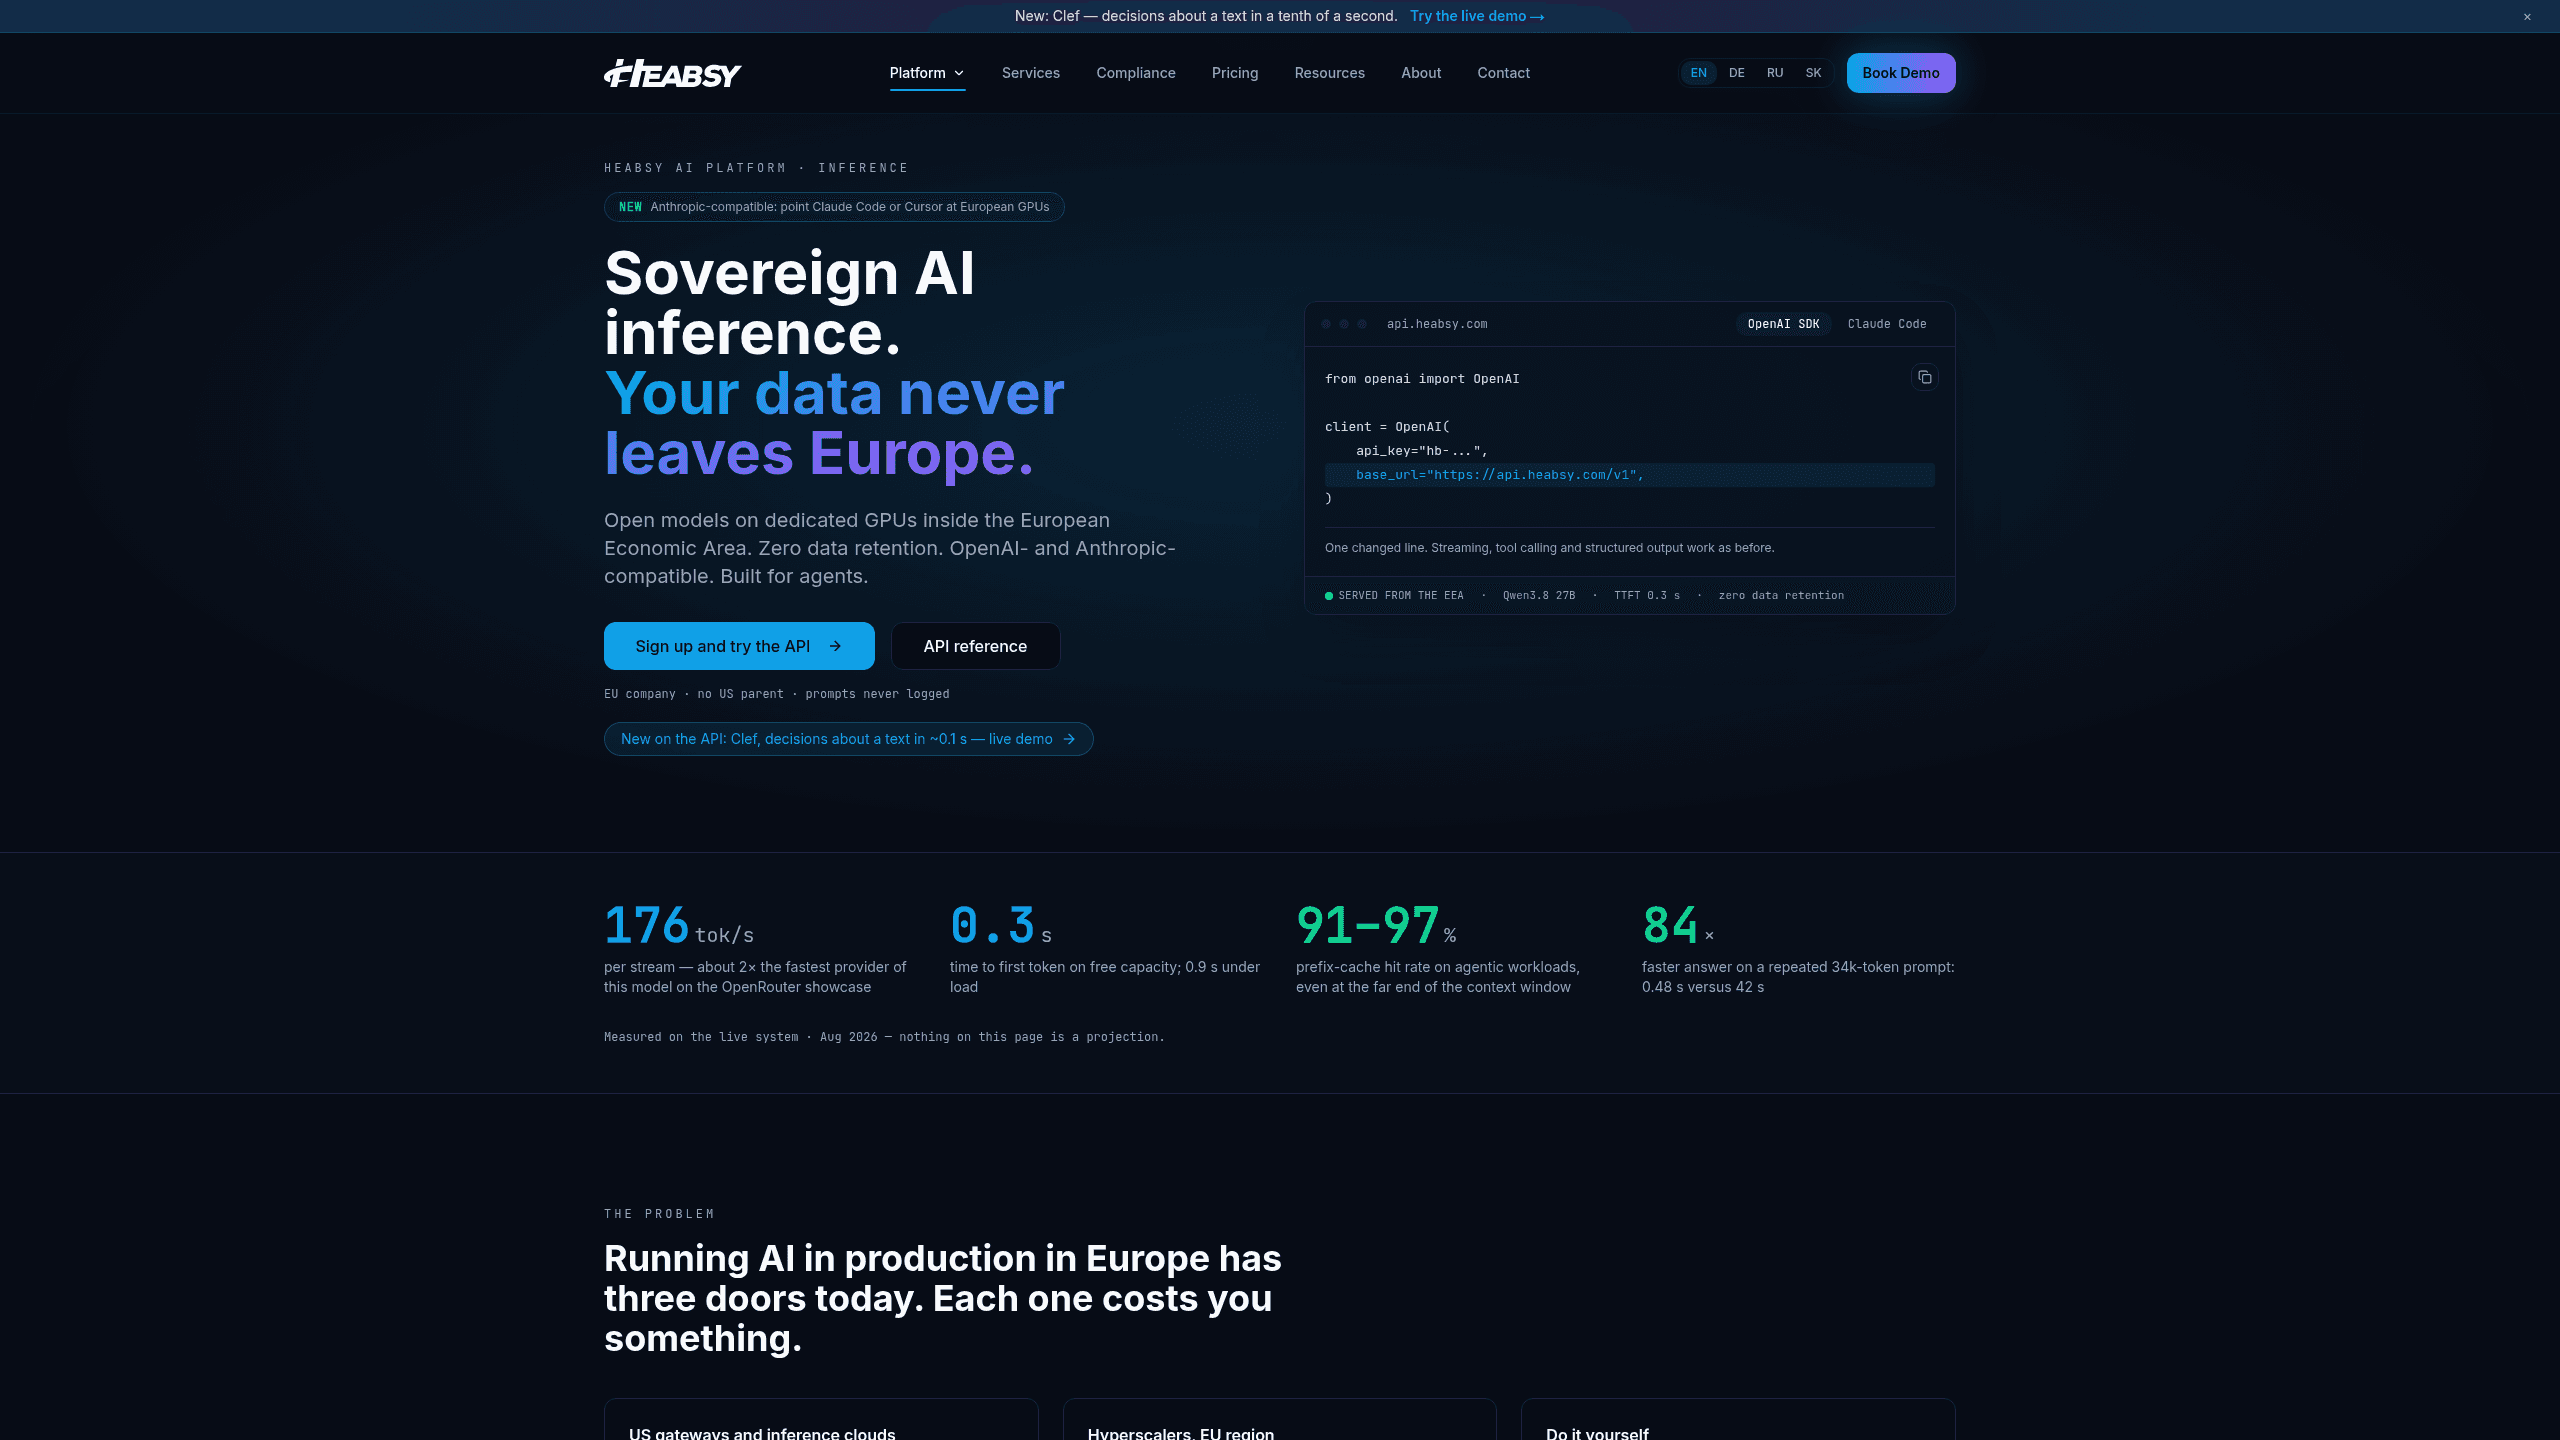
Heabsy AI Inference is an AI inference platform for regulated-industry teams that serves open models through OpenAI-compatible and Anthropic-compatible endpoints. It supports chat completions, SSE streaming, tool calling, structured output, and prefix caching, with per-key budgets and a usage dashboard. The flagship model runs on dedicated EEA GPUs; the rest of the catalog is routed through global providers and may run outside the EEA. The API is billed per million tokens with no minimum spend; separate fixed-price implementation projects start at €5K (Starter) and €25K (Growth), with Enterprise on custom annual contracts.
Last verifiedHow we evaluate
At a glance
- Heabsy AI Inference is best for regulated-industry teams who need compatible API access without moving data outside their infrastructure.
- Enterprise Custom/ annual contract
- 30 days
- Yes — The platform exposes an OpenAI-compatible API at api.heabsy.com/v1 and an API reference at api.heabsy.com/docs, with chat completions, SSE streaming, tool calling, and structured output.
What it actually is
Heabsy AI Inference (api.heabsy.com, console at platform.heabsy.com) is the API arm of FEYA, s.r.o., a Slovak company (Bratislava registered office, IČO 47887541) that otherwise sells bespoke RAG/agent implementation projects to mid-sized regulated companies in Austria and Germany. The API is OpenAI- and Anthropic-compatible — point an existing SDK at api.heabsy.com/v1 with a model ID from the catalog and it works. One model, Qwen3.8 27B, is the flagship: Heabsy operates the GPUs for it itself, inside the EEA (datacenters in NL, DE, DK, NO, BG, per the live catalog API). Everything else — about 30 other open-weight models from DeepSeek, Qwen, Mistral, Meta, Google, NVIDIA and others — is routed through third-party global providers under Heabsy's own contract: one DPA, one invoice, but not Heabsy's own hardware.
Pricing is per-token, not the project fees shown elsewhere on the site
The API is billed per million tokens, with a separate price for input, cached input and output on every model — confirmed against the live price list at heabsy.com/models (updated 12 September 2026) and the machine-readable catalog at api.heabsy.com/openrouter/v1/models. Prices range from $0.04/M input on the cheapest routed model to $2.20/M input on Kimi K3; the flagship Qwen3.8 27B is $0.40/M input, $0.05/M cached input, $3.00/M output. No minimum spend, no subscription. The €5K (Starter) and €25K (Growth) figures that also appear on heabsy.com are a separate product — fixed-price AI implementation consulting projects (document audits, RAG deployments, integration work) — and have nothing to do with the inference API's token pricing.
Not certified, and the vendor says so directly
Heabsy's own security page states plainly, under a “Not certified” label: “Are you ISO 27001 or SOC 2 certified? No.” It adds that it can help a customer build toward their own certification but does not claim either standard for itself. There is no 30-day or other free trial advertised anywhere on the platform, models or pricing pages — access is a self-service signup and pay-per-token from the first request.
EEA-only processing applies to the flagship model, not the whole catalog
Heabsy's own FAQ page states it directly: “Does not claim that every model reachable through its API is processed in the EU: routed catalogue models may run outside the EEA, and each model page says so.” The live model table bears this out — most routed models (DeepSeek, Llama, GLM, Nemotron, Kimi K3 and others) are tagged “Outside EEA”; a handful of routed models, including some uncensored/fine-tuned variants, are tagged “EEA only.” A buyer who needs strict EEA-only processing across every model they call should check the Processing column on heabsy.com/models before relying on any single model, rather than assuming the EEA promise extends to the whole catalog because the flagship is EEA-hosted.
The live catalog goes beyond the public models page
The public models page lists 31 models. Querying the same live catalog endpoint the site uses (api.heabsy.com/openrouter/v1/models) returns several additional, currently-queryable model IDs not listed on that page: refusal-removed (“uncensored,” “obliterated,” “abliterated”) variants of Qwen3.8 27B, DeepSeek-V4.1-Flash, GLM-5.3-Flash and MiMo V2.6 Flash; an in-house “Heabsy V1” assistant model; and a model called “CyberHeabsy,” whose own API description markets it for “red-teaming, security auditing, reverse engineering, and advanced malware analysis.” None of these appear on heabsy.com/models or elsewhere on the public site. This isn't a security flaw — the key only reaches what it's issued for — but a buyer reviewing the published catalog before signing is reviewing a narrower list than what the API key can actually call.
How much does Heabsy AI Inference cost?
| Plan | Price | What's included |
|---|---|---|
| Starter | from €5K/ per project |
|
| Growth | from €25K/ per project |
|
| Enterprise | Custom/ annual contract |
|
Frequently asked questions
What is Heabsy AI Inference?
Heabsy AI Inference is an AI inference platform for regulated-industry teams that serves open models through OpenAI-compatible and Anthropic-compatible endpoints. It supports chat completions, SSE streaming, tool calling, structured output, and prefix caching, with per-key budgets and a usage dashboard. The flagship model runs on dedicated EEA GPUs; the rest of the catalog is routed through global providers and may run outside the EEA. The API is billed per million tokens with no minimum spend; separate fixed-price implementation projects start at €5K (Starter) and €25K (Growth), with Enterprise on custom annual contracts.
How much does Heabsy AI Inference cost? Is it free?
The API is billed per million tokens with no minimum spend. Separately, Heabsy sells fixed-price AI implementation projects: Starter from €5K, Growth from €25K, Enterprise on a custom annual contract — these are consulting projects, not API plans.
What is Heabsy AI Inference used for? Who is it for?
Heabsy AI Inference is used for Sovereign AI inference, Zero data retention, and OpenAI-compatible API. It's built for Platform engineers, Security and compliance teams, and Developers using Claude Code or Cursor.
Does Heabsy AI Inference have an API and what does it integrate with?
The platform exposes an OpenAI-compatible API at api.heabsy.com/v1 and an API reference at api.heabsy.com/docs, with chat completions, SSE streaming, tool calling, and structured output. It integrates with Claude Code, Cursor, Cline.
How does Heabsy AI Inference handle my data? Does it train on it?
No, Heabsy AI Inference does not train on your data. Heabsy AI Inference operates under a zero-data-retention policy.
Editor's read
Check whether your deployment needs on-premise installation or EEA-hosted GPUs, since those are the platform's core sovereignty options. If you also need contract-level service terms or named account support, those appear only in the Enterprise tier.

Explore other AI Model Providers


