
At a glance
- Category
- AI model providers
For developers
- Works with
- Kubernetes, Slurm, Slack, Discord, Hugging Face Hub
What is Together AI?
Together AI is an AI-native cloud for AI teams that turns model requests, training jobs, and cluster workloads into managed production infrastructure. It supports serverless inference, batch inference, dedicated model inference, GPU clusters, fine-tuning, evaluations, and observability. The platform supports 200+ models and is used by Cursor, Decagon, and Vercept. Pricing starts with usage-based serverless inference tiers such as GLM-5.3 at $1.40, MiniMax M2.7 at $0.30, and Kimi K3 at $3.00.
What it is, verified today
Together AI (together.ai) is a hosted AI cloud: on-demand serverless inference across 200+ open-source models (confirmed via the models page meta description, which reads 'Browse 200+ models for text, image, video, code, and audio'), batch inference, provisioned throughput, dedicated model/container inference, GPU clusters (H100 through GB300 NVL72), fine-tuning, evaluations, a code sandbox, and managed storage. The company is still actively shipping: its official Python SDK on GitHub was pushed 2 days before this check (togithub.com/togethercomputer/together-python, pushed_at 10 October 2026), and the pricing/blog pages carry an 'On-demand B200s now available' announcement dated this week. This is not a stalled or archived product.
Pricing: genuinely public, but the model names move fast
Together publishes real per-model, per-million-token rates with no 'contact us' wall for the inference tiers — a rarity among the inference resellers in this category. Verified against together.ai/pricing today: MiniMax M2.7 is $0.30 input / $1.20 output per 1M tokens, GLM-5.3 is $1.40 / $4.40, gpt-oss-120B is $0.15 / $0.60, and Kimi K3 (the current flagship Kimi model on serverless inference) is $3.00 / $15.00. GPU clusters are priced hourly per GPU: H100 on-demand is $3.99/hr (down to $3.19/hr on 181+ day reserved terms), B200 is $8.19/hr on-demand; GB200/GB300 NVL72 remain 'contact us' only. Fine-tuning is priced separately and steeply for larger models — fine-tuning GLM-5.2, for example, runs $40 per 1M training tokens with a $60 minimum job charge, against $1.40/1M for just running it. The catch for buyers: the specific model names on the pricing table churn. GLM-5.1, cited in an earlier version of this listing, no longer exists as a model page (404 as of today) — it has been replaced by GLM-5.2 and GLM-5.3 at the same $1.40 price point. Kimi K2.6 has been dropped from the serverless inference table entirely and now appears only in the fine-tuning price list; the current serverless Kimi model is K3, priced roughly 10x higher per token than K2.6 was. Anyone pricing out a workload should re-check the live table at signup rather than quoting a model name from documentation or an old review.
Where it's been proven in production
Together features three customer case studies prominently (homepage 'AI natives build on Together AI' carousel, 12 October 2026): Cursor runs production inference on NVIDIA Blackwell GB200 NVL72 for in-editor latency, with a documented 'days' weights-to-test-endpoint pipeline. Decagon, a voice-AI vendor, reports (on its own case-study page) 'nearly 6x cost reduction per turn compared to closed models like GPT-5 mini' and p95 latency cut from seconds to under 400ms. Vercept reports 92% accuracy versus OpenAI's 18.3% on the ScreenSpot v1 UI-grounding benchmark, plus roughly 30% cost savings versus hyperscalers and sub-24-hour model deployment cycles. These are the vendor's own figures, not independently benchmarked, but they are specific, sourced to named customers, and corroborated by dedicated case-study pages rather than just a logo wall. The broader customer-logo carousel (Zoom, Salesforce, Mozilla, ElevenLabs, DeepMind, SK Telecom, Quora, WordPress, Cognition, among others) is also visible on the live homepage and matches the customer list in Together's own Vanta trust-center description.
Security and compliance
Together AI runs a public, Vanta-hosted trust center at trust.together.ai. As of this check it lists a current SOC 2 Type 2 report (an update was published 17 June 2026) and ISO 27001:2022 certification (announced 29 May 2026), along with named subprocessors (AWS, Google Workspace, Okta, Stripe) and a Data Processing Addendum available on request. This substantiates the SOC 2 tag on this listing.
Trade-offs to weigh
Fine-tuning frontier-sized open models is priced well above running them — fine-tuning GLM-5.2 costs roughly 28x the per-token inference rate, which matters for anyone planning to adapt a large model rather than just call it. The largest GPU hardware (GB200/GB300 NVL72) has no published price at all; only 'contact us'. The only documented uptime figure found on the live site is a 99% SLA tied specifically to the Provisioned Throughput tier — not a platform-wide 99.9% figure, which does not currently appear anywhere on together.ai, docs.together.ai, or the three customer case-study pages checked. And because the per-model pricing table is refreshed frequently (see above), a specific model/price pairing quoted anywhere, including on this listing, should be treated as a snapshot.
Together AI price and terms
Terms
- Free to start
- PartlyLimited free use
The terms in full
The pricing page lists one serverless chat model, Ternary Bonsai 27B, at Free for both input and output tokens as of November 18, 2026. Every other model, GPU, sandbox, storage and fine-tuning line carries a metered price; no free plan or free credit is shown on the page.
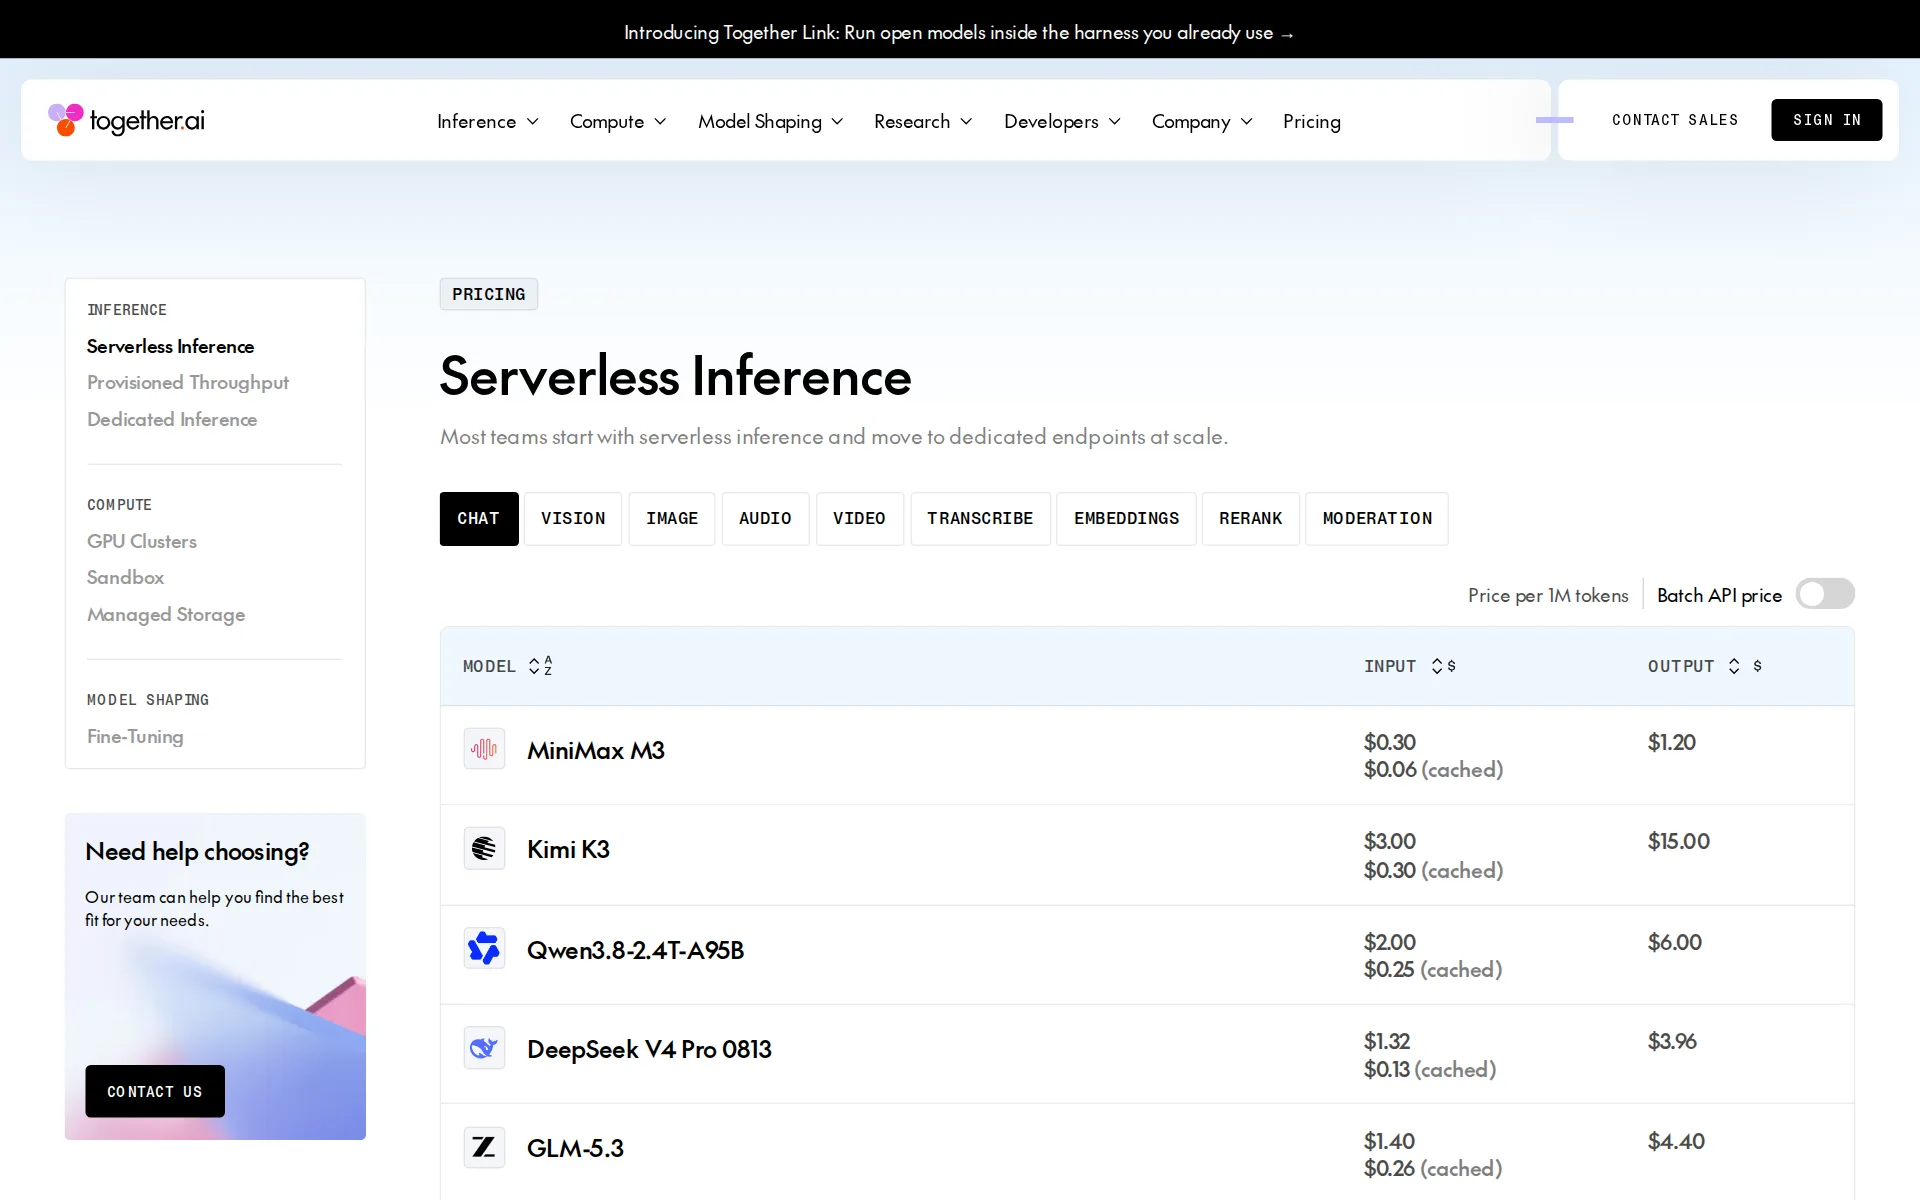
Pricing page, captured
together.ai/pricing, checked
What we checked on Together AI
What the price counts
Priced per use with no subscription plans: serverless models bill per 1M input and output tokens, provisioned throughput per PTU minute, GPUs per GPU hour, sandboxes per vCPU and GiB hour, fine-tuning per 1M training tokens with a per-job minimum charge.
Price per 1M tokens
together.ai/pricingChecked
Free to use
Only a single serverless model, Ternary Bonsai 27B, is listed at Free for input and output tokens; every other product line on the pricing page is metered and paid, and no free plan or credit grant appears there.
Ternary Bonsai 27B Free Free
together.ai/pricingChecked
Open source
48 public repositories on GitHub, none of them the product's code
On the page: github.com/togethercomputer repositories
github.com/togethercomputerChecked by us,
Together AI alternatives
Together AI and Fireworks AI
Together AI beside its alternatives: the price on each one's site and the day it was checked Tool Price Checked Together AI From $0.042 per 1m input tokens Fireworks AI From $0.05 per 1m input tokens

Questions about Together AI
- How much does Together AI cost?
- Together AI costs $0.042 per 1m input tokens. From together.ai/pricing, checked 18 November 2026.
- Does Together AI have an API or an MCP server?
- Together AI has an API.
- What have we checked on Together AI?
- 2 facts, under one heading: What it costs to start.
- How do we check Together AI?
- We hold 2 facts on Together AI, quoted from 1 page. Facts and price last checked 18 November 2026, when we also found the last change.
Together AI price history
We have read the price once so far, on 18 November 2026: from $0.042 per 1m input tokens.
| Price | Plan | First seen | Last seen | Readings | Source |
|---|---|---|---|---|---|
| $0.042 per 1m input tokens | 18 November 2026 | 18 November 2026 | 1 | Pricing page, read 18 November 2026 |
From our research on 18 November 2026. A date is when we read the page, not when the price changed.
Similar to Together AI
- ERIUS PHONERented cloud Android phones, each in its own container, that keep an agent's apps and sign-ins between sessions.
- TinyFishWeb search, page fetching, cloud browsers and goal-driven web automation for AI agents, with search and fetch free.
- SmitheryPublic MCP server registry, now run by Arcade, listing direct vendor MCP URLs after its proxy shut down.
- UI DiscoveryA library of real websites, iOS apps and dashboards with each one's palette, fonts and original build prompt.


From our research
- Best sales agents for marketing teams, and what to checkApollo suits teams starting free, VoiceDrop suits voicemail campaigns, and PipeLime suits hands-off email and LinkedIn prospecting.
- Which browser automation API should you build an agent on?Skyvern, Browserbase, Browser Use, Playwright MCP, Hyperbrowser, and TinyFish compared on credential handling, session isolation, and audits, not speed.
- Clay pricing: every plan, its Actions, Data Credits and rowsWhat Clay's Free, Launch, Growth and Enterprise plans cost, and how many Actions, Data Credits and table rows each one includes.
Is Together AI yours?
Free, and the page then carries the verified owner mark. You confirm it with an email at together.ai. Claim this listing
Report an error if a fact is wrong.